

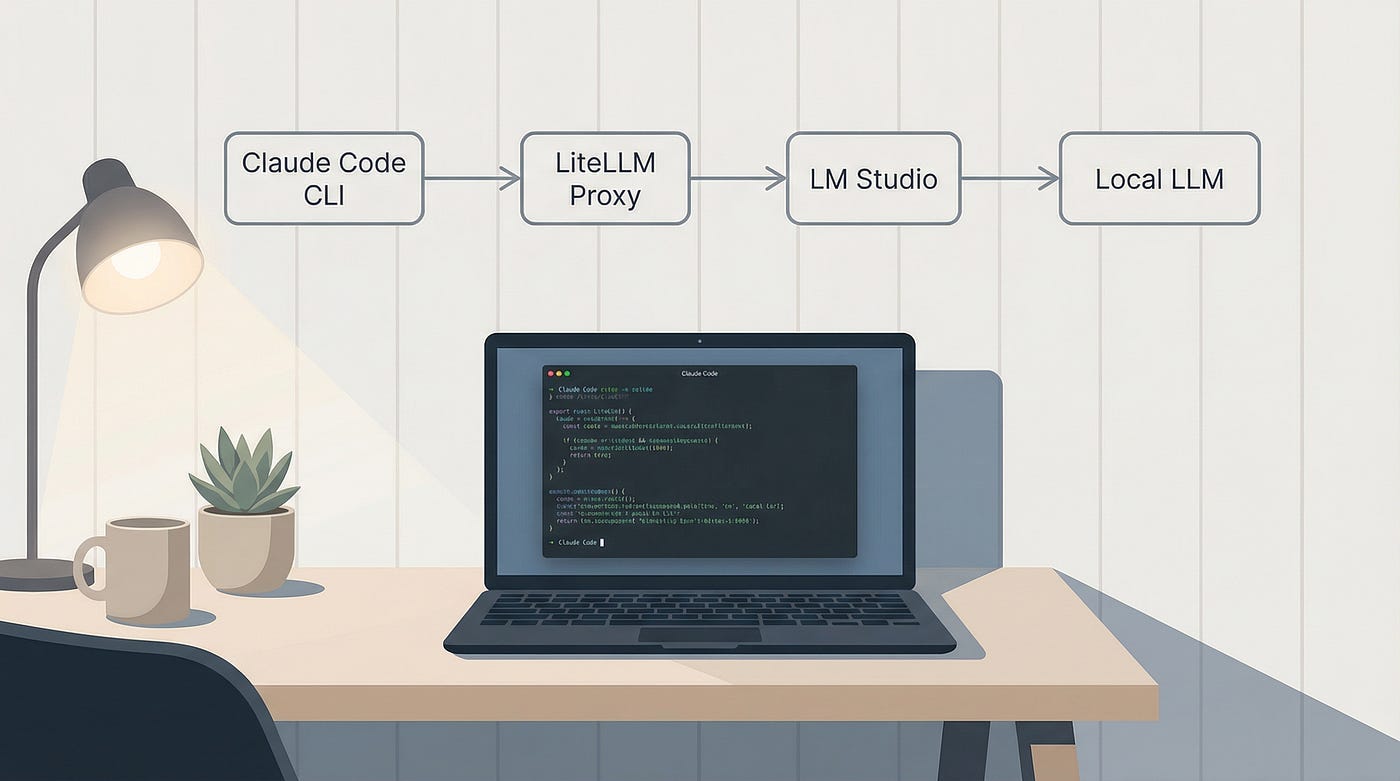
Agentic coding tools are powerful, but they usually come with a cost. Until recently, using Claude Code meant routing every request through Anthropic’s API and paying per token.
That is no longer strictly necessary.
Ollama recently introduced support for running Claude Code locally with open-source models. This is a strong option for Windows, Linux, and macOS Intel users. However, on Apple Silicon (M-series Macs), Ollama provides limited benefits because it does not support MLX models. On Apple Silicon, MLX models are significantly faster and more efficient than GGUF models, meaning Ollama cannot fully utilize the hardware capabilities of M1, M2, or M3 chips.
To solve this, we can use LiteLLM with minimal configuration to make Claude Code compatible with LM Studio, enabling us to run high-performance MLX models locally on Apple Silicon.
In this article, I’ll show how to run Claude Code locally on macOS using:
LM Studio for local LLM inference
Qwen3-Coder-30B, a strong open-source coding model
LiteLLM as an Anthropic-to-OpenAI protocol bridge
Zero cloud usage and zero API cost
This setup works reliably on macOS Apple Silicon, runs entirely offline, and does not require Docker.
If you are using Windows or Linux, you can run Claude Code locally using Ollama without setting up a LiteLLM proxy. For those platforms, refer to the official documentation.
Get All My 8 Books, One Button Away With 60% Off

I have created a bundle for my books and roadmaps, so you can buy everything with just one button and for 40% less than the original price. The bundle features 8 eBooks, including:
What We’re Building?
Claude Code expects the Anthropic Messages API, while most local LLM runtimes expose an OpenAI-compatible API.
The key idea is to insert a lightweight translation layer, so Claude Code can work with a local model.
The final architecture looks like this:
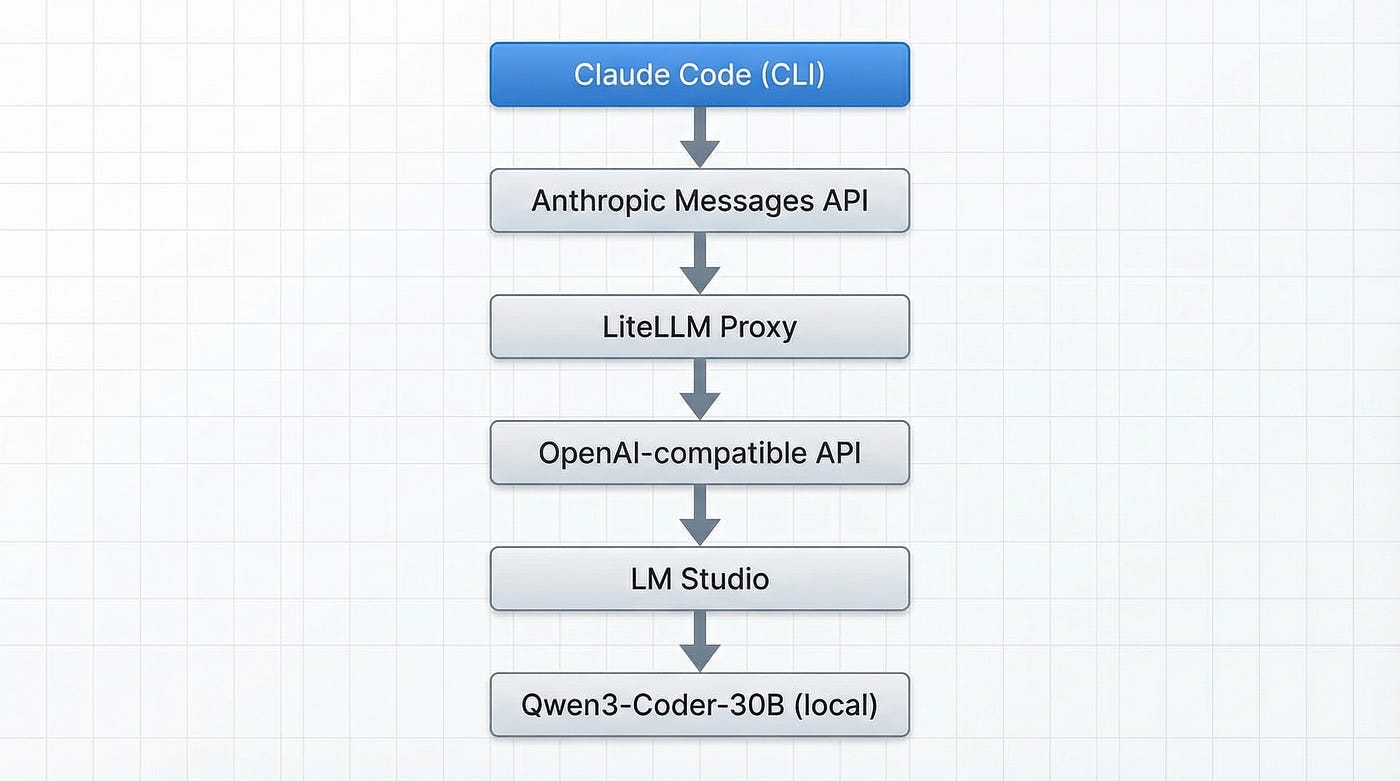
Once this is set up, Claude Code behaves exactly like it does with Anthropic’s cloud — except everything runs on your machine.
Prerequisites
macOS (Apple Silicon works well)
Python 3.10+
Node.js (for Claude Code)
LM Studio installed
Sufficient RAM for a 30B model
Step 1: Set Up LM Studio
Open LM Studio
Download and load the model:
Model name
qwen/qwen3-coder-30b4. Enable the Local Server
5. Confirm the server is running at:
http://localhost:1234/v1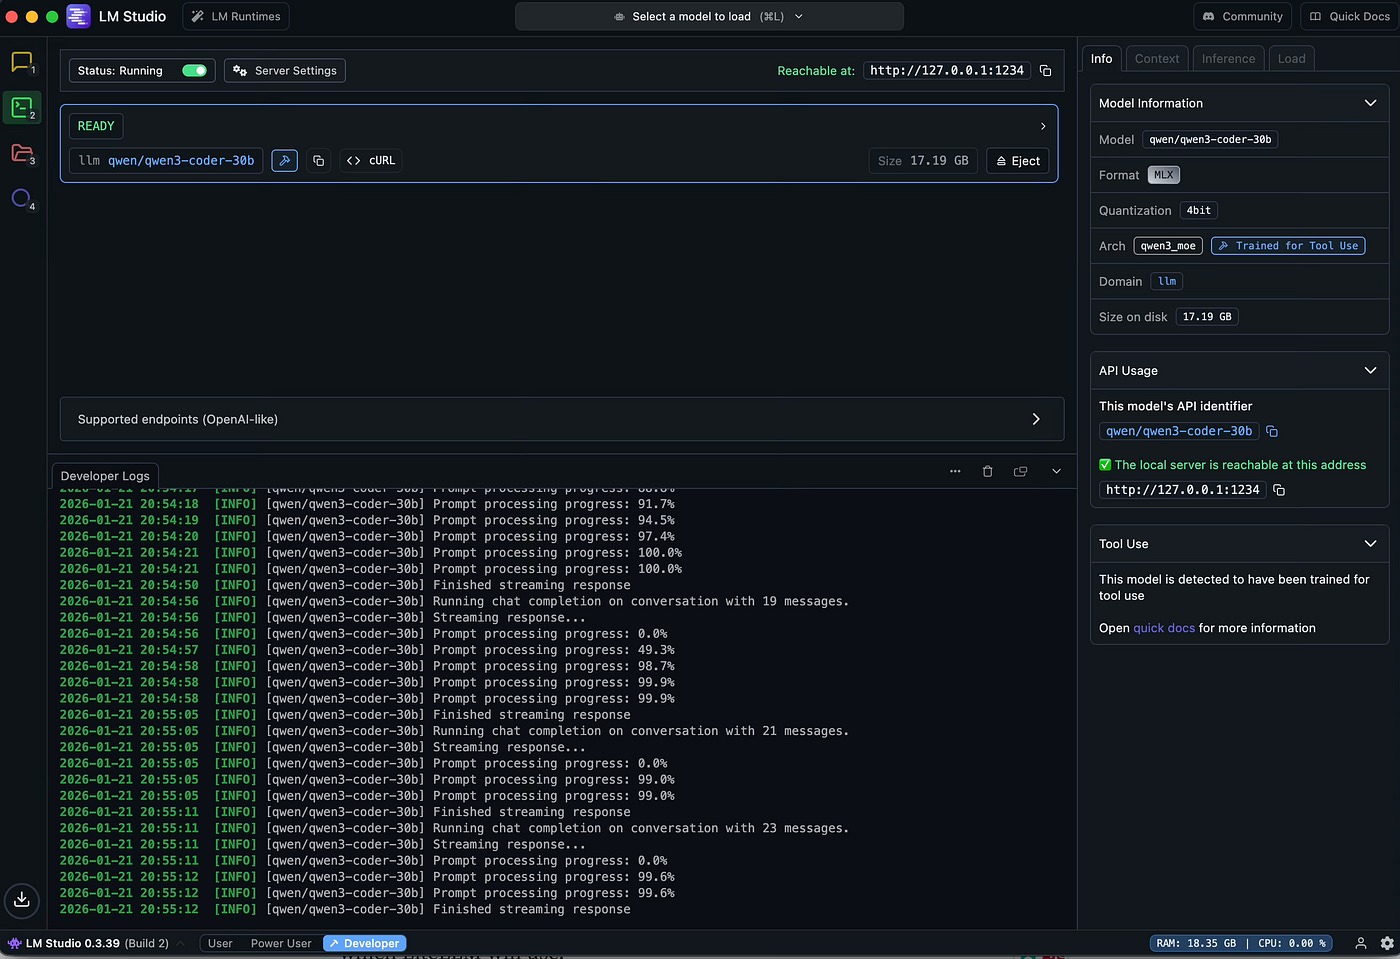
This endpoint exposes an OpenAI-compatible Chat Completions API, which LiteLLM will use.
Step 2: Create a Python Virtual Environment
Create a clean environment for LiteLLM:
mkdir ~/litellm
cd ~/litellm
python3 -m venv venv
source venv/bin/activate
Install LiteLLM with proxy support:
pip install “litellm[proxy]”Step 3: Configure LiteLLM
Create a file called config.yaml:
model_list:
  - model_name: qwen3-coder
    litellm_params:
      model: openai/qwen/qwen3-coder-30b
      api_base: http://localhost:1234/v1
      api_key: lmstudio

  # Claude Code starts with this default model internally
  - model_name: claude-haiku-4-5-20251001
    litellm_params:
      model: openai/qwen/qwen3-coder-30b
      api_base: http://localhost:1234/v1
      api_key: lmstudio

litellm_settings:
  drop_params: true
Why this configuration matters
Model aliasing: Claude Code does not reliably handle model names with slashes.
We expose a clean alias (qwen3-coder) while mapping it to the exact LM Studio model ID.Claude's default model mapping: Claude Code internally starts with
claude-haiku-4-5-20251001. Mapping it avoids startup errors.drop_params: true.Claude Code sends Anthropic-specific parameters that local models do not support. LiteLLM safely removes them.
Step 4: Start the LiteLLM Proxy
From the same directory:

